On-brand posts
96%
pass rateVibe-coded monitoring drowns you in alerts you can’t trust.
TwoTail gives you calibrated LLM judges and proves them against your business outcomes, so you spot problems before your customers do.
On-brand posts
Citations are real
Candidate fit
Personalised opener
Test drive booked
A customer asks the same question three times, then gives up.
It scores a strong candidate 4/10, and only a recruiter would spot it.
It books meetings, but not the ones your customer wanted.
You change the prompt, the model or a tool. One thing gets better, and two quietly get worse.
TwoTail is the agent quality system your growing agent startup deserves. It's built on evals: automated checks that grade every trace.
Hear about issues as they start, not when customers complain.
Every trace scored as it comes in. A Slack alert when a score moves.
Vibe-coded monitoring
With TwoTail
# agent-quality
repeat_question is up on support agent: 11% of traces today, from 4% last week. Mostly billing_dispute.
View 14 tracesMute
Scores your expert agrees with, and a number for how often.
Your expert labels the few traces the judge is least sure about. The judge learns from them.
Vibe-coded monitoring
With TwoTail
candidate_score · 10 of 14 traces labelled
Know which issues hurt your outcomes, and which to ignore.
Eval scores tested against retention, conversion or your customers' results, ranked by impact.
Vibe-coded monitoring
With TwoTail
shopping assistant · northstar: revenue
Know whether a change helps before it ships.
Test sets built from production traces, graded by the same judges.
Vibe-coded monitoring
With TwoTail
model A vs model B
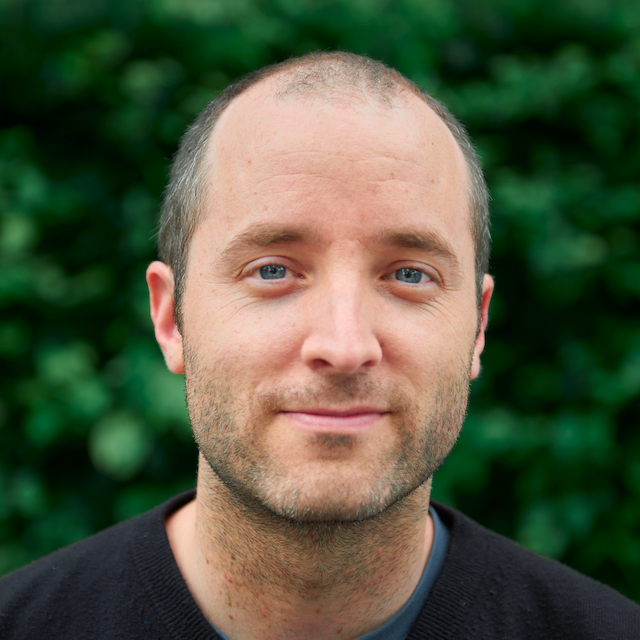
I’ve worked for some of Europe’s highest growth scaleups, and founded 3 AI startups. When you use TwoTail, you get me too. A powerful tool combined with an experienced operator figuring out the perfect way to measure and optimize your agent.
Read the full story
We used to rely on a Claude routine to find issues with our agent, but it was unreliable and I started ignoring it. Now we have evals to measure when agent quality drops - and we are confident that when it pings us on Slack it’s not a false positive.
 Harold

Tim is a deep thinker and brilliant problem solver, I would highly recommend him to anyone trying to solve a multi-faceted issue that may seem daunting, he has the craft to sort it out!
 Xavier
Timothy is an expert in data modeling. With his help, we now have a clear understanding of how users behave. We highly recommend working with him.
 Randy

Because they have so much experience in the field, they proactively find the edge cases and implement systems so those are handled correctly.
 Marlon
TwoTail reads the traces you are already producing. Point OpenTelemetry at it, or turn on the Langfuse integration and leave everything where it is.
prompt
Add TwoTail tracing to this agent.
TwoTail accepts standard OpenTelemetry
spans, no custom conventions required.

## Configuration
endpoint  https://www.twotail.ai/api/v1/traces
header    X-API-Key: tt_live_…
POST https://www.twotail.ai/api/v1/traces
X-API-Key: tt_live_…
Content-Type: application/json

{ "resourceSpans": [ … ] }
connect langfuse
region      EU · cloud.langfuse.com
public key  pk-lf-…
secret key  sk-lf-…
import      last 30 days

[ Connect ]  read-only, nothing moves
You can, and you should. Claude Code reads traces, proposes failure taxonomies, and writes eval criteria well. What it cannot do is tell you whether its judgement is right: no ground truth from you, no agreement rate, a fresh taxonomy on every rerun, and a sample rather than your whole corpus. TwoTail is what it calls to get those. Your agent does the analysis; TwoTail makes it defensible.
Both, on the same judges. In production, TwoTail scores every session, not a sample, so you see what your agent is doing to customers today. Before a release, you run those judges over test sets built from real sessions. Most teams start with production, because that is where the surprises are.
Langfuse gives you somewhere to put scores. It has no opinion about which scores you should have, or whether they mean anything. TwoTail adds the two parts it does not have: labelling queues that pick the few sessions your expert needs to see, and a map from your scores to the business outcomes they move. Most of our customers run TwoTail on top of Langfuse: same OTel feed, different job.
Not out of the box. In specialised fields, frontier judges agree with you as little as 64% of the time. Calibrated against a few hundred well-chosen labels, they hold up, and the agreement rate is visible before you trust a single score.
Your data is stored in isolated Postgres databases with row-level security. Each account's data is fully segregated, and all connections are encrypted in transit.
Plans are priced for growth-stage teams, with a free trial once you're set up. It starts with a quality kickoff. Full details on the pricing page.
30 minutes on how to measure quality for your agent. You leave with a plan: what to measure, how to trace it, and which evals to set up. Yours to keep, whatever you decide.
If it's a fit, we set it up for you within two weeks.
repeat_question handover_missed refund_policy
One span per conversation turn, tool calls as child spans. Sent over OpenTelemetry, or read from your Langfuse feed.
One LLM judge per measure, calibrated on traces your team labels.
Yours to keep, whatever you decide.